Below is the whole chain: face, voice, swapping a face into footage you shot, generating from scratch, translation and lip-sync. With the price of each step and the places I tripped over myself.
What an AI model is made of: a face, a voice, a clip
Let me split this up front, because it causes confusion later. «A clip with my face» is two completely different jobs, handled by different models:
The first gives you realism, because it is real footage. The second gives you freedom, but the picture comes out cleaner and more synthetic.
Step 1. The face: reference photos or a generated look
It starts with a set of reference photos. First non-obvious thing: the models need very few of them. Kling takes four references maximum, and that is a hard cap, not a suggestion. So every «upload 15 photos» instruction you have read applies to training your own model, not to ordinary generation.
I ask myself for 5-8 photos. Not because the model will consume them, but so there is something to pick the best shot from for a given scene.

What actually moves the needle, in order:
If you do not have a face to use
Half the people doing this work with a character who does not exist. There is a second entry point for them: describe the appearance in text and the model renders four shots of the same non-existent person.
There was a technical trap here that I hit while building it. The obvious approach is four requests with the same description and different angles. That gives you four different people, because the model has no parameter that pins the appearance across requests. The only thing that works: generate the first shot, then derive the other three from it, passing it back in as the reference. Then it is one person.
Which is also why there is an «add angles» button: it takes your real photos and fills in the missing views. If you have one good portrait, that is already enough to start.

Step 2. Voice clone
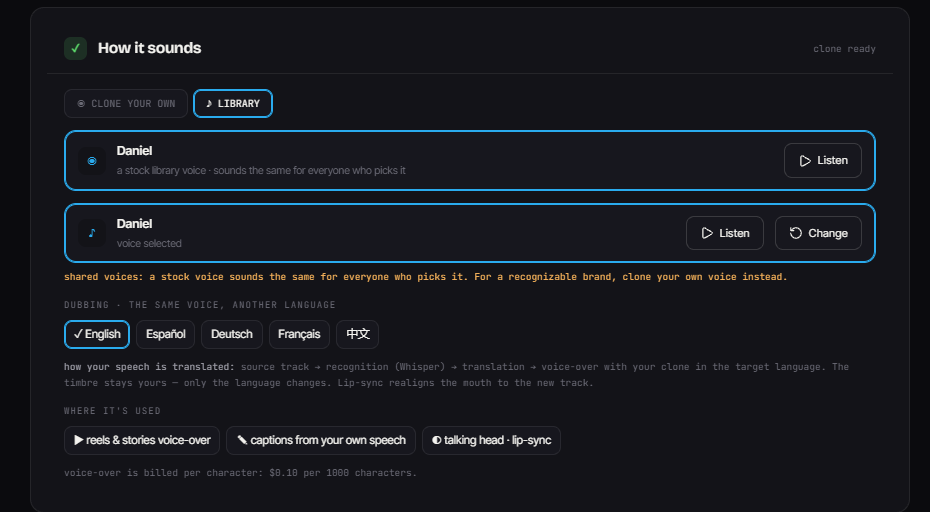
Two routes, and they differ in uniqueness rather than quality:
A minute to a minute and a half is enough for the clone. Read any text in an even voice, no music, no room echo. After that any text is read in your voice, in any language: the clone keeps the timbre, only the language changes.

The library is a couple of dozen stock voices, each one playable before you pick. Enough to start, or for a character who has no voice of their own. Just remember that hundreds of other people will pick the same one: it gives a brand no recognition.
There used to be a third button, «design a voice from a description». I removed it: for three dollars the model produced a result you could not hear before paying, and half the time it was not what you wanted. The clone is cheaper and better.
Step 3. AI face swap video. Here is the main trap
Clip on the timeline, pick the persona, hit the button. And this is where it most often comes out as garbage, with no obvious reason why.
Now think about what is in your first frame. A fade-in. Titles. A wide shot of you walking into a room. The back of your head. In any of those the model has nothing to read, and the swap either does nothing or drifts across the whole clip. And it looks like «the model is bad».
So we take the frame at the playhead. Literally: park the scrubber on a moment where your face is large and clearly visible, and run it from there. That one thing matters more than every other setting combined.

The trick that lifts quality the most
Guides for similar services contain this advice: build your reference photo from the first frame of the target video so the light and the angle match. Then follows a twenty-line prompt you are supposed to copy into a separate image tool, assemble a portrait there and come back.
The advice is completely right. Matching light is the second biggest factor after how large the face is. It is just inconvenient enough by hand that almost nobody does it.
But the clip is already on the timeline. So the frame can be grabbed for you, handed to the model together with the persona photos, and you get the persona in that frame's light and angle. And the swap runs with that.
For us that is the «match the reference to this shot» toggle, on by default. It adds $0.08, about a third of the swap itself. Worth turning off only to save on a rough draft.
Step 4. A clip from scratch: AI avatar from a photo and a prompt
There is no source here, so the prompt becomes the only thing that defines the shot. The face is passed in as a reference you have to mention in the text, otherwise the model does not know who is on screen.
Compare two prompts. Bad:
a person dances in the rain and sings
Working:
@Image1 dances in the rain on a night street,
mid shot, black jacket and jeans, wet hair,
neon reflections in the puddles, camera slowly orbits
The difference is that the second one says who is on screen, what they are wearing, how close the shot is and how the camera moves. Anything you leave out, the model invents for you.
And about singing, because this is the most asked question
This is not one service falling short. Every video model that generates audio invents the voice itself. None of them accept your clone. To get your actual voice you need a three-step chain: generate the video, voice it with the clone, align the lips with lip-sync. And even then a limit remains: speech synthesis does not sing, it reads. Proper singing in your own voice does not exist anywhere right now, and it is worth knowing that before you go looking.
Step 5. Translation and lip-sync
The most underrated case: you have your own clip and you want it in English in your own voice. For that you do not even need a voice clone: the dubbing model lifts the timbre straight off the track. Upload, pick the language, get the same voice in another one.
Now the price, and there is some arithmetic here that matters.
Dubbing is billed per started minute, rounded up. Which means a 19-second clip costs the same as a 59-second one: one full minute. I first priced it pro-rata by seconds and was off by a factor of three. If you plan to translate a lot of short clips, it is cheaper to stitch them together and translate in one batch.
Lip-sync is a separate operation and it is five times more expensive than the translation itself. So we keep it off by default, with that stated plainly. Without it the lips will not match, and for a talking head that is fine, which is how most dubbing services work. Turn it on when the face is close up and the mismatch is obvious.

What this actually costs
I collected these myself against the model pages on fal.ai as of 12 September 2026. They change, so verify, but the order of magnitude is this:
| Operation | Price | How it is counted |
|---|---|---|
| Face swap, 720p | $0.20 | Per clip up to 5 sec, double above |
| Matching the reference to a frame | $0.08 | Per image |
| Generation with a face | $0.14 / sec | With audio. $0.112 without |
| Animating a photo | ~$0.30 for 5 sec | Per second |
| Translation | $0.60 / min | Per started minute, rounded up |
| Lip-sync | $3 / min | $5 for the pro variant |
| Text to speech | $0.10 / 1000 chars | A 30-sec clip is ~$0.05 |
For calibration: one of my 5-second clips with audio came to $0.28. That matched the formula, so the table can be trusted.
Short checklist
If you are starting with X rather than video, there is a companion piece on how to grow on X.
What nobody can do yet
So you do not go looking where there is nothing:
That last point, incidentally, is the main reason this is easier in an editor with a timeline than in a bot. Cutting by scene, running each part and stitching back is simply not something you can do there.
The whole chain from this article lives in Sndwich
The face and the voice are set up in Persona, the swap, the clip and the translation happen in the editor, and every price is shown before you start.
 5 minHow to create an AI influencer: what the job actually is
 6 minWan 3 vs Seedance 2.5: four models, one clip, one winner
 6 minAI video API pricing: we paid twice for the same model and measured it